
In the summer of 2026, the number of documented deepfake cases worldwide reached several million a year — an increase of about 900% in just two years. At the same time, a Microsoft study of 12,500 people, covering almost 287,000 assessments of images generated by DALL·E 3, Midjourney v6, and Stable Diffusion 3, found something sobering: people correctly recognize whether a photo is the work of AI in only 62% of cases — barely above a coin toss. For faces generated by GANs and photos edited with inpainting, the recognition rate fell below 50%, that is, worse than random guessing.
This article is a complete, technical protocol for verifying digital content for AI — photos, video, audio, and text. Instead of yet another list of “7 signs that give away AI” (which, as the data above shows, the human brain applies with an effectiveness close to random anyway), I propose a methodology based on three independent layers of verification, supported by specific tools, some of which are free and available to everyone.
Why “looking at the fingers” is no longer enough
Until recently, AI generators gave themselves away with characteristic errors: an unnatural number of fingers, warped lettering geometry, strange facial symmetry. In 2026, these signals have practically disappeared from the newest models — and yet many guides keep repeating the same outdated tips. Reliable industry sources openly admit: “AI material no longer has six fingers or warped geometry” — you can still sense some intuitive “alarm,” but without technical tools it’s increasingly hard to verify it.
That’s why relying solely on visual analysis is today the weakest of the available verification methods — not the strongest, as popular guides suggest.
The three-layer verification protocol
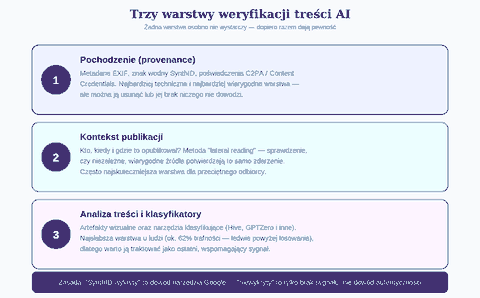
Professionals who verify content (OSINT, investigative journalism, cybersecurity) recommend checking three independent, mutually complementary layers of evidence. None of them gives certainty on its own — only by combining them can you draw a reliable conclusion.
Layer 1: provenance
The first step is to check the file’s technical “pedigree” — metadata, watermarks, and digital credentials.
EXIF metadata. Every photo from a camera or phone contains metadata by default: the device model, the date, the lens settings. A file “straight from the camera” that bears traces of being exported from an AI generator needs explaining. But keep in mind: the absence of EXIF metadata is not proof of AI — most social networks routinely strip this data on upload, regardless of the file’s origin.
SynthID. This is a digital watermarking mechanism developed by Google DeepMind. The watermark is embedded directly in the pixels of an image, the frames of a video, the audio waveform, or the structure of text generated with Google’s tools, and is designed to survive compression, cropping, or a change in resolution. Since its rollout in 2023, Google has marked more than 20 billion generated images with it. The key interpretation rule: a detected SynthID is proof that the file came from a Google tool — but an undetected watermark is just the absence of a signal, never proof of authenticity (it may have been removed by heavy editing, or the file simply wasn’t created in a Google tool).
C2PA and Content Credentials. Coalition for Content Provenance and Authenticity (C2PA) is an open technical standard founded in February 2021 by Adobe, Arm, the BBC, Intel, Microsoft, and Truepic, now also supported by Google, OpenAI, Meta, and Amazon — in January 2026, the standard had more than 6,000 member companies and affiliated entities. C2PA attaches a cryptographically signed “manifest” to the file containing its full history: who created the file, with what tool, and what changes were made. Tampering with the file breaks the digital signature and is immediately detectable. The limitation is similar to SynthID’s: the standard attests to the file’s history, not its truthfulness, and it can be bypassed if the distribution platform strips the metadata.
Layer 2: publication context
The second layer is checking who published the material, when, and for what purpose — a method known to professional verifiers as lateral reading . Instead of analyzing the file itself in isolation from its context, you open a new tab and check whether independent, credible sources confirm the same event at the same time and place. If a supposed recording of an important event doesn’t appear in any reputable media outlet and circulates only on one anonymous account — that’s a warning sign stronger than any pixel analysis. This layer is based on the same principles we described in more detail in the article on comparing different newsrooms’ coverage of the same event.
Layer 3: content analysis and automatic classifiers
Only at the end — not at the beginning — is it worth turning to analysis of the content itself: characteristic visual artifacts (inconsistent shadows and reflections, illogical text in the background, disrupted symmetry) and automatic classification tools. As the Microsoft study mentioned above showed, the human eye is unreliable in this layer, which is why this is exactly where the specialized tools described later in the article add the most value.
The legal context: why this is suddenly so important in 2026
On August 2, 2026, Article 50 of the EU regulation on artificial intelligence (the AI Act)comes into force, imposing specific transparency obligations. Deepfakes — material realistically depicting people, events, or statements that didn’t happen — must be labeled regardless of whether the creator intended to mislead anyone. Providers of generative AI systems are required to mark content in a machine-readable way (with a transitional adjustment period until December 2, 2026, for tools already on the market), and entities publishing AI-generated content on matters of public interest must label it, unless it has undergone careful editorial review by a human. Penalties for non-compliance reach 15 million euros or 3% of a company’s global annual turnover — whichever is higher.
For the average internet user, this means that in the coming years more and more content will carry provenance labels that are readable by machines (though not necessarily by humans) — which makes knowing the tools that read these labels (described below) a practical skill, not just a technical curiosity.
Tools for verifying AI content — a practical overview
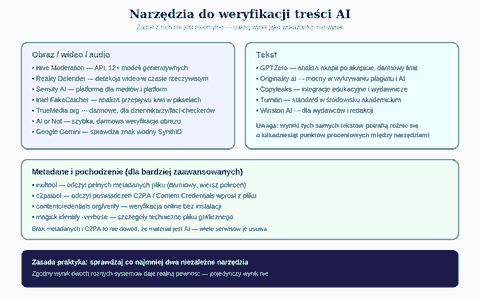
Below is a list of real, working tools, grouped by content type. None of them is infallible — independent tests show discrepancies of several dozen percentage points between competing products, so the key rule is: check with at least two independent tools.
Tools for images, video, and audio
- Hive Moderation — a content moderation API platform used by Reddit and Giphy, among others. It recognizes images generated by more than 12 different model architectures (Midjourney, DALL-E 3, Stable Diffusion, Flux) and can indicate which engine was probably used to create an image.
- Reality Defender — specializes in detecting video deepfakes in real time; it offers a browser extension for scanning websites and local files.
- Sensity AI — an enterprise-class platform for media and large internet platforms, handling large volumes of content.
- Intel FakeCatcher — the most technically interesting solution: it analyzes the photoplethysmographic signal, that is, subtle changes in skin color caused by blood flow, which synthetic faces don’t reproduce convincingly. Available mainly to institutional partners.
- TrueMedia.org — a free tool created with journalists and fact-checkers in mind.
- AI or Not — a quick, free tool for initial verification of a single image or audio recording.
- Google Gemini — the app lets you check for a SynthID watermark directly in an uploaded file.
Tools for text
- GPTZero — the most popular AI text detector, offering a free allowance (10,000 words a month) and paragraph-level analysis. In independent tests in 2026, it showed high effectiveness in detecting text generated by the newest models, although earlier independent tests recorded results much lower than those claimed by the manufacturer — a discrepancy of several dozen percentage points between tests is the norm in this industry.
- Originality.ai — a popular tool combining plagiarism and AI content detection, stronger with older models than with the newest ones.
- Copyleaks and Turnitin — widely used in academia and publishing.
- Winston AI — aimed mainly at publishers and newsrooms verifying the originality of text.
An important caveat: the same texts, run through different detectors, can get wildly different scores — in some comparisons, the discrepancy reached more than 60 percentage points between tools for the same text. None of these products should be treated as a final verdict, especially in high-stakes contexts (e.g., accusations of academic dishonesty).
Tools for reading metadata and provenance
- exiftool — a free command-line tool for reading the full metadata of an image or video file.
- c2patool — the official tool for reading C2PA / Content Credentials directly from a file.
- contentcredentials.org/verify — a browser-based version of Content Credentials verification, no installation required.
- magick identify -verbose (ImageMagick) — a detailed technical analysis of an image file’s structure.
Why no tool should be trusted uncritically
The AI detector market is growing by several dozen percent a year, and with it the spread in quality is growing. Independent tests in 2026 show that the accuracy claimed by manufacturers (often 95–99%) is sometimes significantly lower in practical, independent tests, and false positive rates (wrongly flagging human work as AI) usually range between 5 and 12%, depending on the tool and the type of content. This means that even a good tool can wrongly accuse authentic material — which is why the result of a single detector should never be the sole basis for serious decisions (e.g., rejecting a student’s paper or accusing someone of publishing a fake).
The safest practice: treat each tool as one voice in a larger evidentiary process, combine content analysis with the provenance and context layers, and always look for agreement between at least two independent sources of verification.
A practical step-by-step protocol
- Secure the original. Before you start the analysis, save the file in its original quality — screenshots or compressed copies lose metadata and make further verification harder.
- Check the metadata and C2PA with a tool such as exiftool or c2patool / contentcredentials.org.
- Check for a watermarkif you suspect Google tools — using the Gemini app.
- Apply lateral reading — check whether independent, credible sources confirm the same material or event.
- Run at least two independent classifiers (e.g., one for images and one for text, or two competing tools of the same type) and compare the results.
- Draw a conclusion proportional to the evidence. A consistent result across all three layers gives high confidence; contradictory or ambiguous signals justify only a cautious conclusion, not a categorical claim.
Frequently asked questions
Is there a single tool that will recognize every type of AI content?
No. Detecting images, video, audio, and text are separate technical problems, solved with different methods. Even large platforms like Hive or Reality Defender combine many specialized models under one interface rather than relying on one universal algorithm.
Does the absence of an AI Act label mean the material is definitely not AI-generated?
No. The labeling obligation is coming into force gradually (from August and December 2026) and applies mainly to providers and entities operating in the EU — creators outside the EU or those acting unlawfully won’t always comply with it.
Should you trust the 99% result a detector gives you?
Treat the accuracy claimed by the manufacturer with limited trust — independent tests regularly show results that differ significantly from marketing materials. What counts above all is agreement with results from other, independent sources of verification.
Summary
Detecting AI-generated content in 2026 is no longer a matter of a trained eye, but of a systematic process based on three complementary layers: the file’s technical provenance (metadata, SynthID, C2PA), the publication context (lateral reading), and — only at the end — content analysis supported by specialized tools. No single method, including any commercial detector, gives one hundred percent certainty. The upcoming provisions of the EU AI Act will change the landscape of content labeling, but responsibility for critically verifying what we see online will remain — as it has so far — with the audience.